FROM AN RPA SCRIPT TO AN AI AGENT: WHY AUTOMATION NEEDS A DEDICATED BROWSER RUNTIME
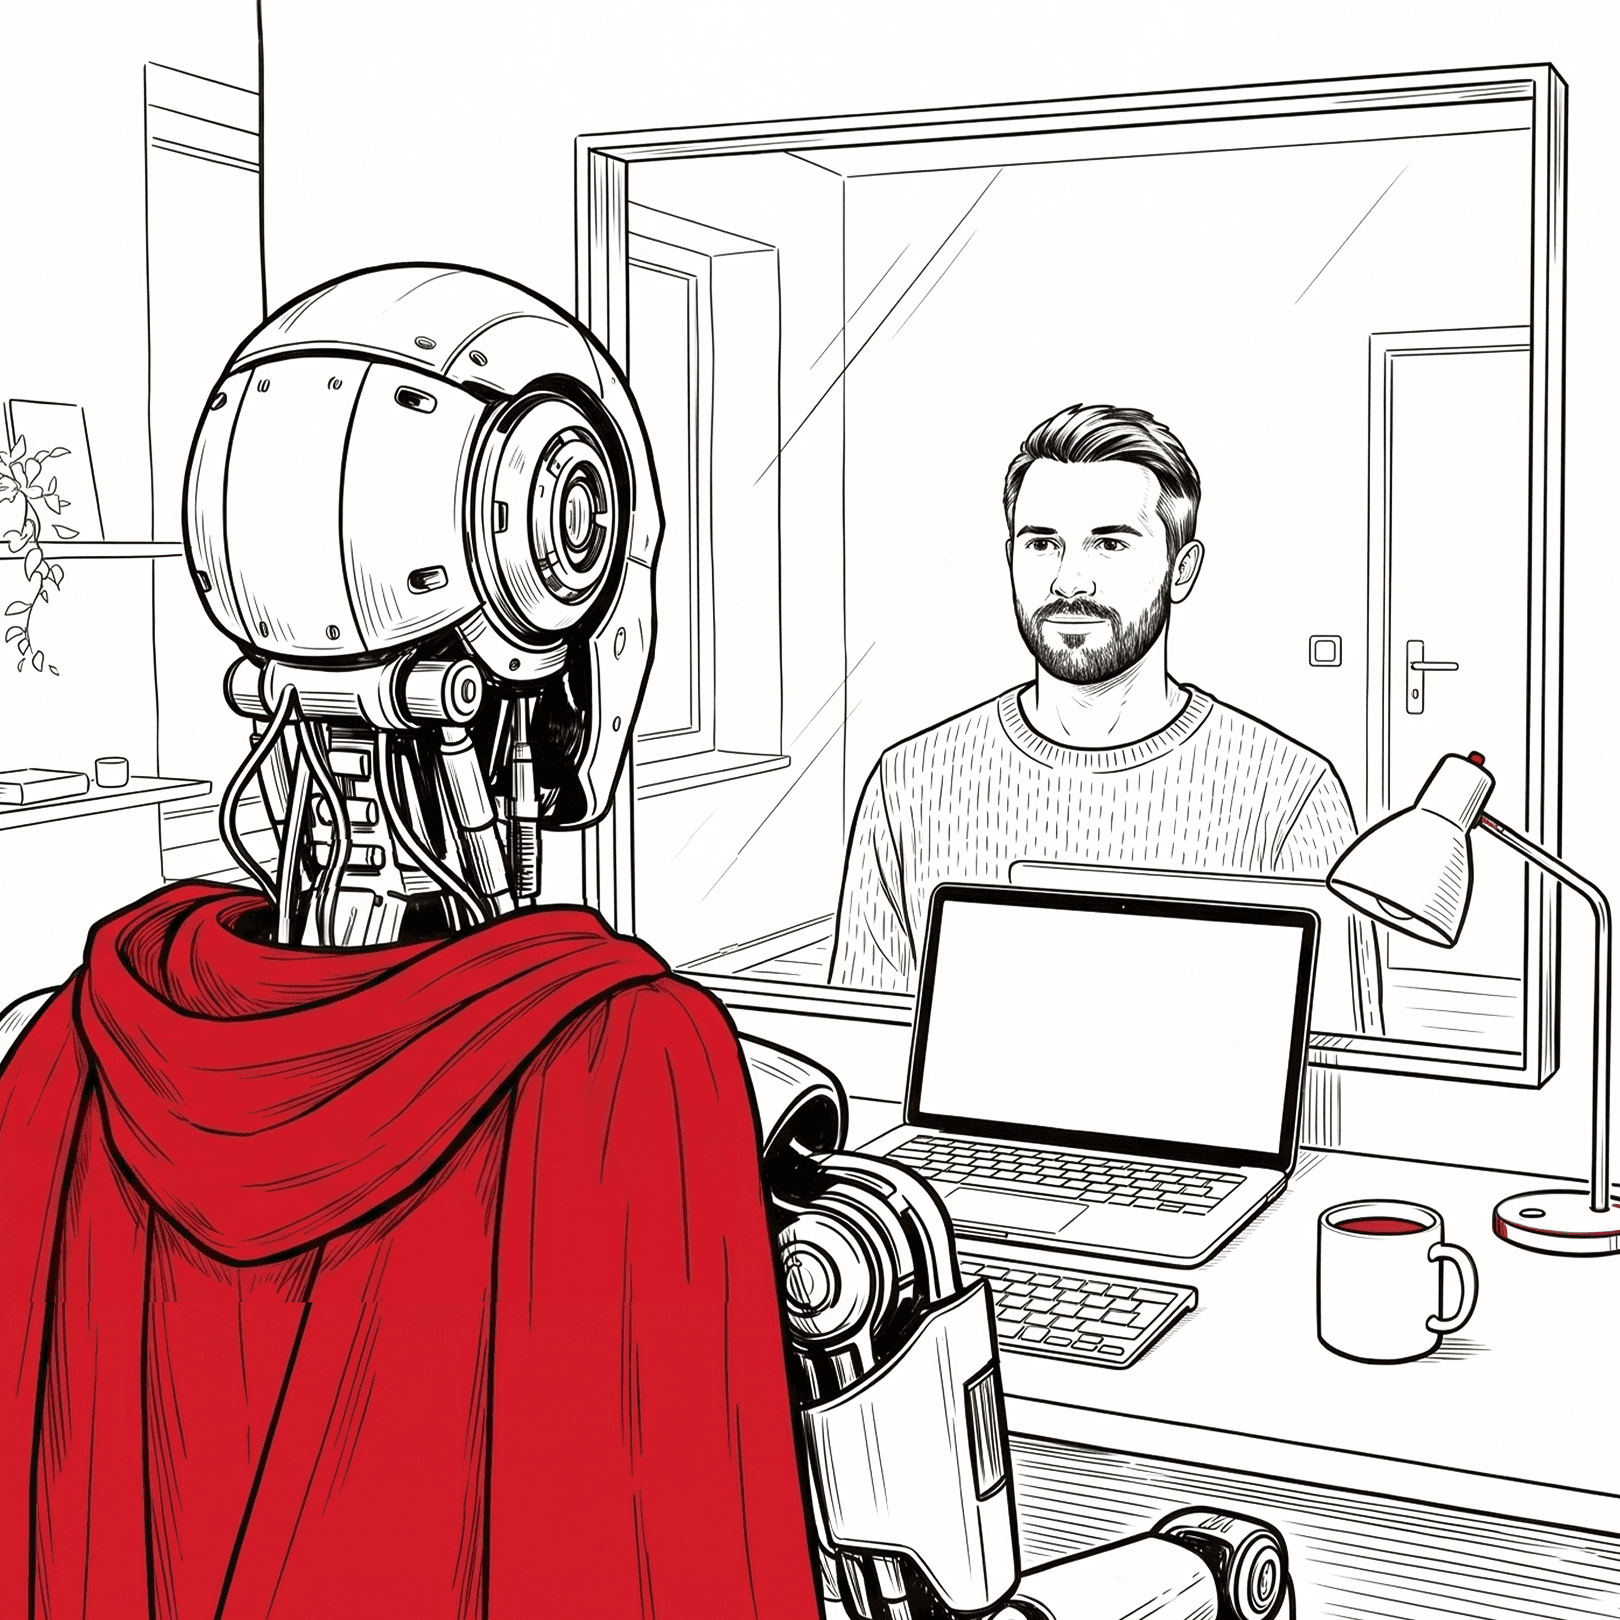
Today, you don't have to be a developer to automate work in a browser. One person writes a program, another builds a workflow in a visual no-code service, and a third simply asks an AI agent: “Open the website, find the information I need, and prepare a brief summary.” A vibe coder can build such a workflow with the help of model prompts without even knowing how the browser finds a button on the page. But ultimately, all these approaches converge at the same point: the website is controlled not by a person, but by a program. It opens pages, clicks buttons, enters text, and reads content.
Author:
Dmitrii Vasilev
Category:
articles
Publication date:
Intro
Imagine a routine task. The browser navigates to the right section, fills out a form, and clicks a button. Everything works on a local computer. But after moving the workflow to a server or running it through an agent, instead of the familiar page you get a message saying “Checking your browser,” a CAPTCHA, or an access-denied page.
The first thought is that something broke: the button changed, the page didn't load in time, or the automation chose the wrong action. But sometimes all the commands are still correct. The problem occurs earlier: the website decides that a program is controlling the browser and doesn't allow the process to continue.
This situation isn't specific to any one technology. Developers, testers, automation specialists, and people who work with AI agents without writing code can all run into it.
In this article, we'll look at:
- why a website may be wary of an automated browser
- why this doesn't make Selenium and Playwright bad tools
- what problem CloakBrowser solves in RPA, automated testing, and other scenarios
- how AI agents work with browsers
- why CloakBrowser MCP is needed in this setup
One important caveat: this is about permitted automation—testing, working with your own systems, researching publicly available data, and other scenarios that don't violate the law or a website's rules.
Automation Can Take Many Forms, But the Problem Is the Same
In this article, I'll use “browser automation” to mean any way of delegating work to a browser: a pre-written script, a visual no-code workflow, or an AI agent that decides what to do next on its own.
From the user's perspective, the difference between these approaches is significant. In one case, you have to describe every action yourself; in another, it's enough to formulate a goal in ordinary language. But from the website's perspective, the difference may be much smaller: in every case, the browser receives programmatic commands.
This is what Selenium and Playwright are designed for. They can open pages, find elements, click buttons, enter text, upload files, take screenshots, and verify results.
A user of an AI agent may never work with these tools directly. Nevertheless, a similar mechanism is often hidden inside the system that carries out their request.
In other words, they answer the question:
How do we perform the required action in the browser?
An anti-bot system answers a different question:
Can this browser session be trusted?
That's why the paradox arises. From the automation perspective, everything may be working perfectly: the page opened, the button was found, and the click command was sent. But the website has already decided to show an additional verification step or restrict access.
The protection system doesn't know the visitor's intentions. A legitimate corporate bot and a malicious program may look similar to it. The website sees not the purpose of the automation, but a set of technical and behavioral signals.
What Exactly Does the Website See?
A website doesn't see the screen through human eyes. Instead, it receives a wide range of information about the browser, device, network, and current visit.
Sometimes the browser itself tells the website that it is being controlled by a program. One technical example is the navigator.webdriver property. But systems such as Cloudflare don't rely on a single signal; they examine multiple pieces of data about the browser, network, visit history, and the results of additional checks. This approach is described in more detail in Cloudflare's documentation.
It's similar to checking a passenger at an airport. An employee compares the person's photo, ID, ticket, itinerary, and behavior. One plausible detail won't help if the others contradict it.
Broadly speaking, these signals can be divided into four groups.
Browser Settings
A website can obtain, directly or indirectly, information about the operating system, screen size, language, time zone, available fonts, and graphics characteristics. Together, these data form what is known as a browser fingerprint.
A fingerprint isn't necessarily unique by itself, nor does it necessarily indicate automation. What matters more is how well its individual parts agree with one another.
Control Method
An automated browser may differ in its launch characteristics, available features, or command patterns. Some signals are directly visible, while others can only be detected by comparing multiple parameters.
Network and Region
The website sees the visitor's IP address and approximate location. It may take the address's reputation into account and compare the region with the browser's language and time zone.
A mismatch doesn't prove anything by itself: people travel, use VPNs, and change their settings. But combined with other signals, it can influence the decision.
History and Behavior
A person doesn't click ten buttons within a single millisecond and rarely opens hundreds of identical pages at perfectly even intervals. That's why a system may consider the speed of actions, navigation sequence, cookies, session age, and request frequency.

The decision is usually based on a combination of signals, rather than a single parameter.
This leads to an important conclusion: removing one obvious signal isn't necessarily enough. If the remaining parameters don't form a coherent picture, the session may still look unusual.
CloakBrowser in RPA, Automated Testing, and Other Automation
Now let's move from the general problem to scenarios in which the sequence of actions is predetermined.
RPA stands for robotic process automation. Instead of an employee, a program opens websites and applications, transfers data, fills out forms, collects reports, and performs other routine tasks. Such a robot can be written in Python or JavaScript, built in a dedicated RPA platform, or configured with almost no code.
But RPA is only one example. Browsers are used in similar ways for other tasks as well:
|
Scenario |
What the browser does |
|
RPA workflow |
Works with corporate portals, forms, and reports |
|
Automated test |
Repeats user actions and verifies the result |
|
Collection of permitted public data |
Opens pages and extracts the required information |
|
Monitoring |
Periodically checks whether a page is available or whether its content has changed |
|
Internal workflow |
Performs operations in an admin panel or another web interface |
In code-based automation, Selenium, Playwright, or Puppeteer are often used to control the browser. RPA platforms may have their own browser modules, but the website still evaluates the browser that has been launched and its environment.
Even if an AI assistant helped write the workflow, it may still be an ordinary predefined program when it runs. We'll return to agents that make decisions on the fly in a separate section below.
In all of these cases, the website ultimately sees a browser controlled by a program.
Why Selenium and Playwright Don't Solve the Whole Problem
Selenium and Playwright are mature and useful tools. They were designed to control browsers, automate testing, and reproduce user workflows. Their job is to execute commands reliably, not to guarantee that a website will accept the automation as a normal visitor.
The developers of security systems recognize this distinction as well. For example, Cloudflare's Turnstile anti-bot documentation explicitly states that Selenium and Playwright may be detected as automation tools. For testing your own website, Cloudflare recommends using dedicated test keys.
And that's the right first choice. If we control the website, it's better to configure a test mode, a separate environment, or authorized access than to try to bypass our own protection.
A specialized browser is worth considering in a different situation: the automation is permitted, the workflow is written correctly, but we can't modify the website being tested and are running into issues related to the browser environment.
Is Simply Showing a Browser Window Enough?
On a server, a browser often runs without a visible window—this is called headless mode. There can indeed be differences between headed and headless runs. But simply displaying a window doesn't turn an automated session into a normal one: the network, settings, history, and control method remain.
Is It Enough to Change the Name of the Browser and System?
The User-Agent is a string that the browser uses to identify itself to a website: it reports the browser name, version, and operating system.
It's easy to change. But it's like putting a new sticker on a suitcase: the label may say “London,” while the suitcase contains a ticket to Warsaw and a map of another city.
For example, a browser may identify itself as running on Windows while simultaneously reporting fonts and graphics parameters characteristic of Linux. Each detail may look normal on its own, but together they raise questions.
Some extensions change only specific pieces of information available to the website. That can be useful, but it isn't always enough: the protection system correlates different data points and notices inconsistencies between them.

CloakBrowser operates at a different level: it doesn't replace the workflow or Playwright; it changes the browser environment.
What CloakBrowser Changes
CloakBrowser is a modified version of Chromium. Google Chrome, Microsoft Edge, and many other browsers are based on Chromium.
According to the developers' description, the project's main idea is to change, inside the browser, some of the data that websites receive about the screen, graphics, fonts, device, and control method, rather than simply applying settings on top of an already running program. To continue the suitcase analogy, this isn't a new sticker—it's a change to the suitcase's construction at the factory.
CloakBrowser is compatible with Playwright and another popular browser automation tool, Puppeteer. Therefore, an existing workflow can often be migrated without being completely rewritten.
The project's documentation also describes:
- persistent profiles that preserve cookies and session state
- synchronization of the language and time zone with the region from which the browser connects to the website
- a mode that simulates character-by-character typing, mouse movements, and gradual scrolling
- support for running on major desktop operating systems
It's important to distinguish the project's capabilities from its claimed results. The project page includes tests conducted by its own developers, but this isn't a guarantee for every website. Protection systems are constantly updated and take server-side data into account, which the browser doesn't control.
How AI Agents Work with Browsers
In the previous section, we mostly discussed workflows with a predefined route. It doesn't matter whether they were written by a developer, assembled by a no-code user, or generated by an AI assistant: when they run, the sequence of actions is already defined.
A browser AI agent works differently. It receives a goal in ordinary language, examines the page, and decides for itself what to do next. For example:
Open the websites of three services, find the terms of their free plans, and prepare a comparison table.
The user doesn't have to specify in advance where the relevant link is or how the page is structured. That's precisely why browser agents are interesting not only to developers but also to vibe coders: you only need to describe the desired outcome, while the agent builds the sequence of navigation and clicks as it works.
Agents need browsers to research public sources, work with pages whose content only appears after the page loads, test interfaces, navigate documentation, and perform operations in internal admin panels.
But the model's intelligence doesn't change the browser's properties. An agent may understand a page perfectly and choose the right button, while the website still sees an automated session.
Put simply, the model is the “brain,” while the browser is the “body.” A smarter brain doesn't change the body's technical characteristics.

The way actions are selected changes, but in both cases the website evaluates the browser session.
How an Agent Gets Access to a Browser: Playwright MCP
For an agent to use a browser, it needs a clear set of commands. That's what Playwright MCP provides.
MCP, or Model Context Protocol, is an open protocol that allows an AI agent to connect to external tools. You can think of it as a universal connector: through it, the agent gets commands for opening a page, clicking a button, entering text, and reading content.
Playwright MCP provides the agent with a list of page elements and their purposes: where a heading, link, field, or button is located. This means the model doesn't have to rely solely on a screenshot of the screen.
For most tasks, that's enough. If a website works normally with an automated browser, there's no need to complicate the setup.
By default, Playwright MCP launches a regular supported browser. Its job is to give the agent browser actions, not to change the signals used by a website to evaluate automation.
What CloakBrowser MCP Adds
Playwright MCP solves the question of “how do we give an agent the ability to control a browser?” But it doesn't change the browser-environment problem itself. If a permitted workflow encounters an additional verification step, the agent ends up in the same situation as an RPA robot or automated test.
CloakBrowser MCP is my independent open-source project under the MIT license. It is not an official CloakHQ component.
It doesn't make the model smarter or give it any new logic. Its purpose is to preserve the familiar Playwright MCP commands while running them in CloakBrowser.
Playwright MCP itself remains responsible for interacting with the page. CloakBrowser MCP prepares the browser, connects the components, and passes the agent's commands through. It also provides diagnostics to help verify that the setup is working.
This connection can also be configured manually: Playwright MCP allows you to specify a different browser. CloakBrowser MCP provides a ready-made integration that:
- prepares CloakBrowser to launch without manually configuring the entire setup
- preserves the familiar Playwright MCP tools
- helps verify the browser and its environment
- supports profiles, regional settings, and more natural input
- allows local operation or operation through a network connection

The commands stay familiar; the browser environment changes. Changing the browser environment doesn't eliminate the influence of the network, behavior, or the rules of a particular website.
More details about the project's architecture are available in the architecture documentation.
|
Question |
Playwright MCP |
CloakBrowser MCP |
|
Which browser is launched? |
A regular supported browser |
CloakBrowser |
|
Are the agent's commands changed? |
Uses Playwright MCP browser commands |
Browser commands are preserved, with additional diagnostic commands |
|
When should you choose it? |
For ordinary browser automation |
When a permitted workflow requires a different browser environment |
How to Connect CloakBrowser MCP
CloakBrowser MCP is added to an agent as an external tool. Here are two commands for technical readers.
Launch it locally:
npx -y cloakbrowser-mcp@latest
Connect it to Codex CLI:
codex mcp add cloakbrowser -- npx -y cloakbrowser-mcp@latest
Current requirements, built-in diagnostics, Docker-based deployment, and other connection methods are described in the getting started guide. It's important to check the documentation because Node.js, Playwright MCP, and CloakBrowser versions change over time.
For a safe demonstration, you can give the agent a neutral task:
Open an authorized diagnostic page, read the available information about the browser, and save a screenshot. Don't submit or change anything without confirmation.
You can then repeat the same task using regular Playwright MCP and compare the environments.
Browser AI Agent Security
An AI agent can click the wrong button, misunderstand some text, or continue working after an unexpected change to the page. Sending forms, publishing content, deleting data, and making payments should require human confirmation.
A page may also contain a malicious instruction designed to alter the agent's task: for example, it may tell the agent to ignore the original request or send data somewhere else. That's why a browser agent is best run:
- in an isolated environment
- without a personal browser profile
- without unnecessary secrets or files
- with a restricted list of allowed websites
- with an action log
- with confirmation required for operations that modify data
If CloakBrowser MCP can be accessed from other computers, that access should be protected with a login or key, an encrypted connection, and restrictions on who can use it.
General Limitations
CloakBrowser and CloakBrowser MCP solve only part of the overall problem.
The Browser Isn't the Only Source of Signals
A website's decision is influenced by the IP address, network reputation, account history, cookies, request frequency, and server-side rules. Changing the browser environment doesn't eliminate these checks.
Results Change Over Time
Chromium, automation tools, and anti-bot systems are constantly updated. A successful run today doesn't guarantee the same result a month from now. That's why repeatable tests matter more than a single impressive screenshot.
Technical Capability Doesn't Mean Permission
You need to consider a service's rules, rate limits, and personal-data requirements. For a third-party website, an official API is almost always preferable if it provides the functionality you need.
Final Thoughts
When choosing tools, it's useful to separate two independent questions.
The first is who determines the sequence of actions. In traditional automation, the route is usually predefined. An AI agent receives a goal and chooses the next steps itself.
The second is what browser environment those actions run in. Regular Chromium is suitable for most tasks. CloakBrowser can be considered when a permitted workflow is hindered by the characteristics of an automated session.
The roles of the components remain clear: the workflow or agent determines what needs to be done; Selenium or Playwright tells the browser how to do it; and the browser itself creates the environment that the website sees. MCP connects the AI agent to browser tools.
That's why Playwright MCP and CloakBrowser MCP shouldn't be viewed as two competing sets of commands. CloakBrowser MCP preserves the Playwright MCP tools but prepares them to run in a different browser environment.
And even then, this isn't a magic button. The approach needs to be tested in your own environment, used responsibly, and evaluated based on repeatable results.
Sources and Documentation
- Selenium WebDriver documentation
- W3C WebDriver specification
- Playwright documentation
- Playwright MCP documentation
- Cloudflare Turnstile testing
- CloakBrowser repository
- CloakBrowser binary license
- CloakBrowser MCP repository
- CloakBrowser MCP architecture
- Playwright MCP vs CloakBrowser MCP comparison
- How Cloudflare detects automated traffic
- Browser configuration in Playwright MCP